
Automatic recovery without endless restarts
A restart can restore useful work or repeat the same failure. Give recovery a clear target, limited authority, a durable attempt budget and a result you can verify.
Published 27 October 2026. Hostwatch engineering review; implementation limits are stated below.
Define the recovery contract before enabling it
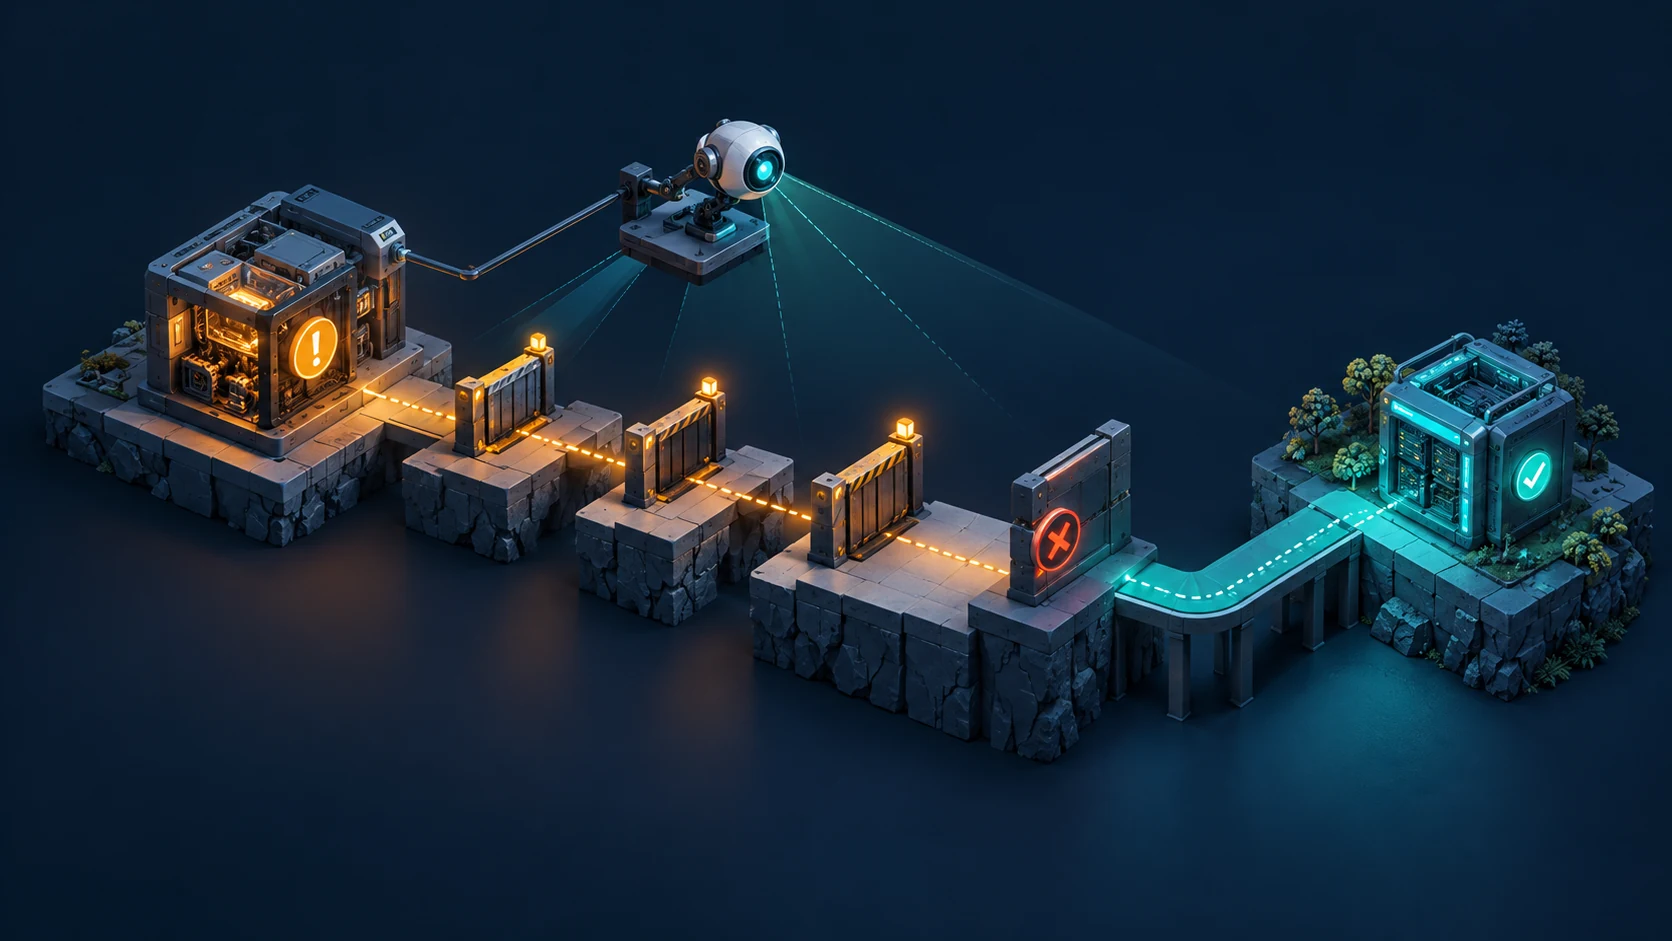
Start with one application on one station. Name its owner, the useful work it performs, the failure signal and the action that is allowed to follow. A desktop assistant, a background agent and a public API have different operating contexts. A policy should identify the installed target precisely, say when recovery becomes armed and explain how an operator can suspend it. Keep automatic recovery disabled until those choices have been reviewed. This makes the first activation a deliberate operational change with a visible scope.
Write the expected result beside the action. Relaunching an application should lead to an observable running instance and an appropriate functional check. Restarting a worker should restore progress on its assigned work. Include a startup grace period, delay between attempts, maximum attempts within a defined window and an escalation owner. Record the policy revision with every action. Someone reviewing the incident later should be able to tell which decision was permitted at the time and why the supervisor used it.
Separate exit, stalled work and missing observations
A process that exited gives a supervisor a relatively direct signal. A process that remains present can still be stalled, waiting for a dependency or showing an unusable interface. Define responsiveness with an application-specific assertion: a local health response, advancing work checkpoint or bounded test operation. Process presence alone establishes only that a matching process exists. For a graphical application, do not assume that its window opening means a session is authenticated or a conversation can continue. These boundaries belong in the status explanation.
Missing telemetry needs its own state. A disconnected phone, expired monitoring session or unavailable network route does not establish that the remote application crashed. Compare a local observation when the architecture supports one, preserve its timestamp and show the gap. Require enough consecutive evidence to reject a transient failure before a disruptive action. Keep maintenance and intentional shutdown recognizable, so a recovery rule does not reopen an application the owner has deliberately closed without making that behavior explicit.
Preserve the first failure before changing state
Capture a bounded diagnostic record before the first restart. Useful fields include station and target identity, observation time, application revision where available, exit reason, recent error context and relevant resource pressure. Record which checks failed and which still passed. Keep authentication material and private conversation content out of routine recovery logs. The goal is enough evidence to explain the action and investigate recurrence, with a retention limit that remains affordable during repeated failures.
Also inspect conditions that a relaunch cannot repair. Full storage, an invalid configuration, an unavailable required dependency or rejected credentials may survive every attempt. A restart can briefly hide these conditions while consuming more resources. Attach a clear escalation reason when the same evidence repeats. Keep the original failure available after recovery; replacing it with the newest successful sample makes an incident harder to diagnose and encourages the same unexplained intervention next time.
Before relaunching a writer, establish what happens to work already in progress. A request may have committed its change before the client lost contact. Follow the application’s documented replay and checkpoint behavior, and preserve any operation identity needed to resolve uncertainty. Recovery should not blindly resubmit a payment, duplicate a queued job or start a second worker against exclusive state.
Give one supervisor responsibility for each action
A recovery mechanism needs a failure boundary outside the application it watches. If both disappear together, the application cannot arrange its own relaunch. Use an appropriate operating-system supervisor for the recovery helper, then define which layer owns application restarts. Avoid two independent supervisors repeatedly acting on the same target. During maintenance, the operator needs a predictable way to stop automatic action without discovering that another layer immediately recreates the process. Document the installed supervision chain and its intended behavior.
On Linux, systemd.service documents restart conditions and the delay between attempts through Restart and RestartSec. The on-failure mode covers specified failure conditions; an explicit manager stop does not trigger that restart policy. Inspect the installed manager’s documentation and effective unit configuration before choosing settings. Application-level automation should account for the existing policy. Keep remote controls restricted to known installed targets and bounded fields, with the authority to change a policy separate from ordinary read access.
Treat the attempt budget as durable state
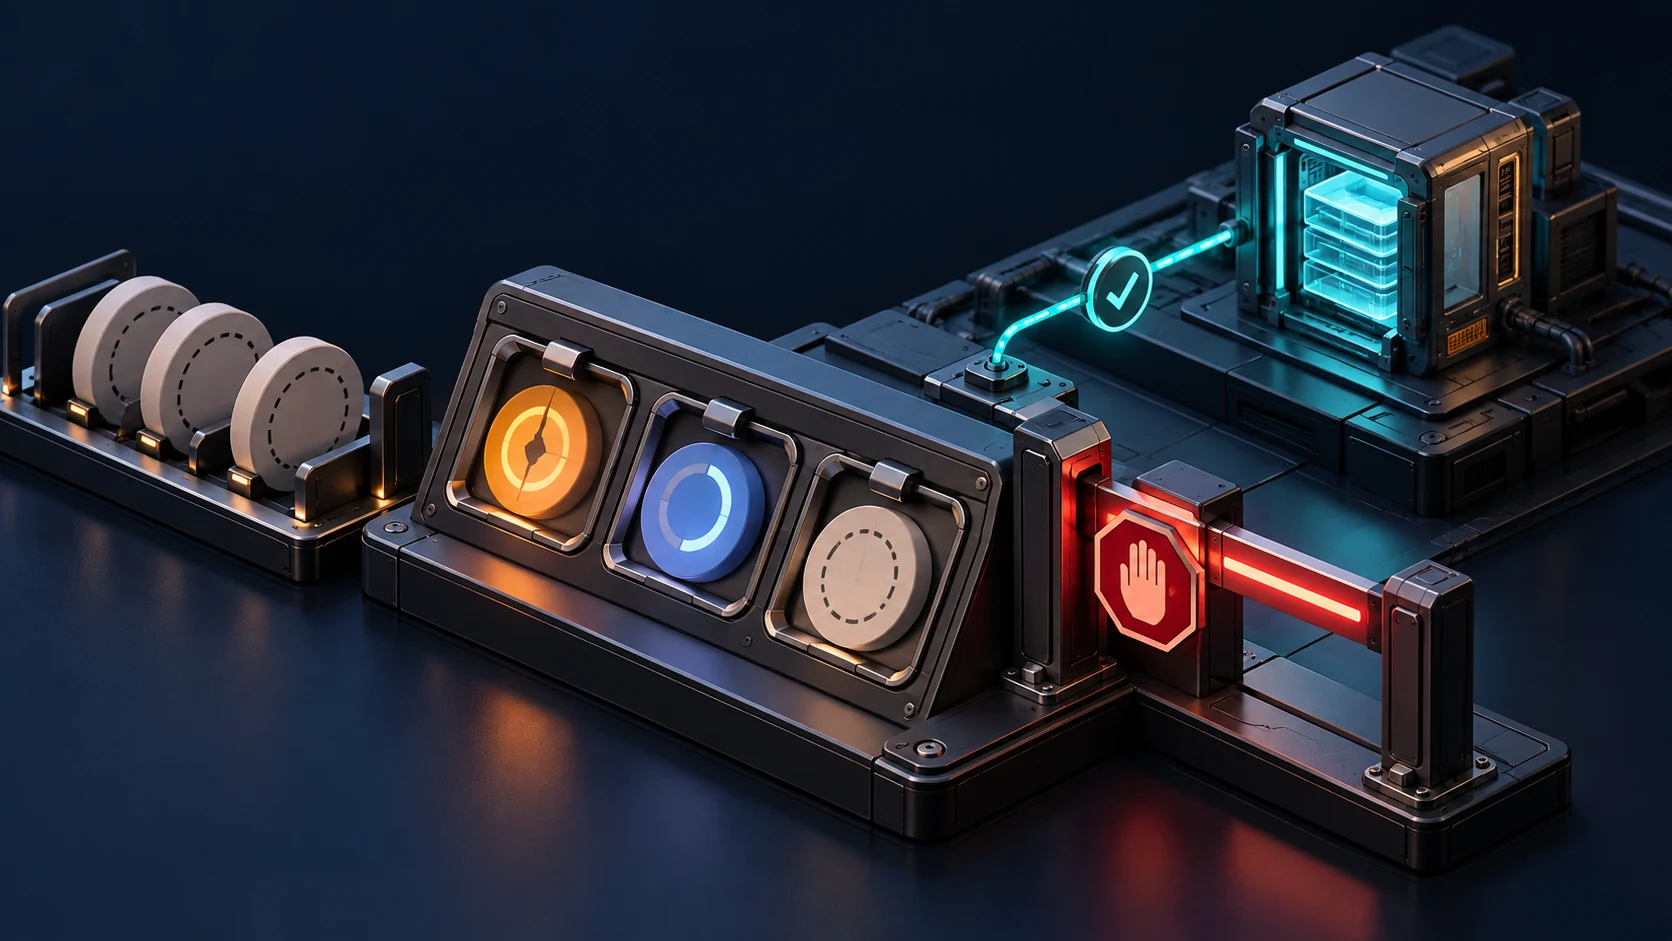
A delay reduces immediate repetition, while a finite attempt budget limits accumulated disruption. Both matter. For illustration, a team might allow three attempts in an hour with a minute between attempts, then require review. Those numbers need validation against the application’s startup time and failure cost. Preserve the attempt record before execution so a helper crash or lost response cannot erase spent attempts. A supervisor restart should not silently create a fresh budget for the same unresolved incident.
The systemd unit reference describes start rate limiting through StartLimitIntervalSec and StartLimitBurst. Check the actual implementation’s scope and reset behavior when translating an operational policy into configuration. A fleet can also benefit from staggered recovery attempts when a shared dependency returns, avoiding simultaneous reconnect pressure. Once the budget is exhausted, expose that state, keep the reason visible and notify the owner. Resuming automation should follow a reviewed condition, with the previous attempts retained in history.
Consider a relay repeatedly failing because its required credential expired. The first restart consumes one attempt and returns the same authorization failure. Later attempts should remain attributable to that incident, with the exhausted budget visible. The owner can repair the credential, run a bounded verification and deliberately resume recovery. A growing restart count without a useful outcome is an escalation signal that needs investigation.
Verify useful recovery after the process returns
Treat action completion and application recovery as separate observations. Record that the relaunch request completed, then check the target after its expected initialization period. Use the original useful operation where practical. An API should satisfy its response contract; a worker should demonstrate bounded progress; a relay should complete an authorized message exchange. Keep verification deadlines explicit. A healthy process with an unavailable dependency can remain unable to complete the operation that caused the incident.
Require an appropriate period of stable results before closing the incident. Report an unknown outcome when the controller loses contact during an action, and inspect the target before repeating it. Repeating an uncertain action under a new identifier can multiply disruption. Preserve action identity, attempt number, policy revision and verification evidence together. This history distinguishes a recovered interruption from repeated unsuccessful relaunches and gives the next operator a concrete place to continue.
Plan Mac startup around the actual user session
Startup and recovery answer different questions. Startup defines when an installed component should first launch; recovery defines what happens after an observed failure. Apple’s archived launchd guide distinguishes system daemons from per-user agents started with a login session. Check the current system’s installed configuration and supported interfaces. A graphical application needs the correct user context, access to its own data and any required interactive sign-in. A background process running before login does not establish that these conditions exist.
A reboot can therefore leave a workstation reachable at one layer while its desktop workflow remains unavailable. Apple Support notes that automatic login is unavailable when FileVault is enabled. Document the station’s unlock and login requirements and arrange an attended recovery path when necessary. Keep machine reboot disabled by default until that path has been tested. Reopening an assistant also cannot promise restoration of unsaved work, an interrupted tool action or an expired application session.
Make whole-machine recovery a separate policy
A whole-machine reboot affects every workload and needs its own trigger, authority, grace period, daily budget and recovery plan. Use local evidence appropriate to that decision. Internet reachability alone is a poor trigger because a remote routing failure may leave the machine and its applications working normally. Account for active writes, shutdown behavior and how the operator will regain access. A failed application should not automatically authorize a more disruptive action outside the reviewed policy.
A completely frozen kernel cannot execute an ordinary user-space recovery helper. Hardware watchdogs and out-of-band management have different capabilities and prerequisites. The Linux watchdog documentation explains hardware reset behavior and driver differences; its historical API discussion is not a universal deployment recipe. Verify support on the specific station and test recovery under controlled conditions.
Rehearse the stop condition as carefully as recovery
Exercise a disposable test target before enabling recovery for important work. Observe one controlled exit, confirm the action record and verify the result. Then simulate repeated failure and confirm that the budget stops further attempts. Test disabling during cooldown, a missing target and unavailable observations. Keep the exercise isolated from customer sessions and real writes.
Include a deliberate maintenance exercise. Pause recovery, stop the target and confirm it stays stopped while the operator inspects it. Then restore the intended startup state and observe the next failure using a fresh timestamp. Check that a helper restart preserves the remaining budget and that the notification reaches the named owner. Document the tested station, software versions and results so the next change has a reliable comparison. Keep the original policy revision available too.
Review the policy after application or operating-system changes. Publish an actionable handoff: what failed, what ran, which checks recovered, why automation stopped and who owns the next decision. Bounded automation earns trust when its limits remain visible during failure.
How Hostwatch applies these boundaries
Hostwatch exposes Recovery & startup per station through the website and iPhone app. Owners configure supported installed targets, restart-on-exit, startup, cooldown and an hourly attempt limit. New target policies start disabled. The independent recovery helper runs under launchd or systemd, so a node agent crash does not remove its own recovery mechanism. Target availability comes from the selected station; the interface does not turn an arbitrary application name into an executable command.
The current helper preserves attempts across its own restarts and retains bounded action history. Its GUI application checks establish process presence, so a running ChatGPT or Claude process is not a measurement of interface responsiveness or successful conversation delivery. For the Hostwatch agent, a configured local health probe provides another signal. Enabled recovery can also reopen an application deliberately quit by its user. Review that consequence before choosing the policy for a personal workstation.
Machine reboot remains a separate, disabled-by-default capability requiring installed privileged support and explicit acknowledgement that local unlock may be necessary. The user-level Mac installation has no reboot privilege. A frozen kernel still needs an appropriate hardware or external recovery path. Hostwatch brings policy, observed state and action evidence together; application-specific functional verification remains an additional responsibility. Choose a station, inspect its supported targets and current supervision, save a bounded policy, and verify the readback before relying on unattended recovery.
Automate a known recovery action within a finite budget. Preserve the failure, verify useful work, and keep startup, application recovery and whole-machine reboot as separate decisions.
Further reading
- systemd.service: restart conditions, delay and readiness ↗
- systemd.unit: start rate limits ↗
- Apple archived developer guide: launch daemons and agents ↗
- Apple Support: automatic login requirements ↗
- Linux kernel: hardware watchdog concepts and driver differences ↗
- Hostwatch: recovery and startup per station ↗
- Hostwatch: checking useful service health ↗