
PostgreSQL connection exhaustion: find the queue before raising the limit
Quiet CPUs do not explain where a database request waits. Inspect application pools, pooler admission, backend ownership and transaction blockers before increasing concurrency or a server-wide limit.
Published 5 November 2026. Hostwatch engineering review; implementation limits are stated below.
Identify what the timeout was waiting for
A request can time out before PostgreSQL receives a query. It may be waiting for an application pool connection, a pooler slot, a database login, a lock or an upstream response after the transaction has already finished. These waits can produce similar customer symptoms while the database CPU graph looks ordinary. Begin with the exact failure reported by the caller and its timestamp. Preserve the component, connection destination and timeout phase where the client exposes it. A generic database timeout message is a starting point for investigation, not enough evidence to change a server limit or restart every application using the same database.
Draw a compact path from request admission to application worker, client pool, optional pooler and database backend. Mark where each stage queues work and where it stops waiting. Then identify which queue actually grew during the incident. If application pool acquisition fails while the database accepts other clients, the first bottleneck may be entirely inside that component. If new logins fail across components, inspect database and pooler admission separately. Keep the user outcome in view: successful checkouts or completed API calls matter more than a larger number of open sessions. The investigation should explain where useful work stopped progressing before selecting a capacity or code change.
Observe sessions without exposing customer queries
Use an authorized monitoring connection and start with aggregate state rather than dumping every query body. PostgreSQL's activity statistics documentation describes pg_stat_activity, including connection state and wait information, and the permissions governing visibility. Group relevant client backends by application identity, user and state. Record the observation time and database. The name an application supplies is useful attribution, but it is not proof of a trusted identity. Correlate it with known deployments and connection configuration. If permissions hide other sessions' details, preserve that limitation instead of treating null or unavailable fields as evidence that nothing is happening.
Keep the first sample small and repeat it deliberately after an intervention. Raw SQL can contain personal data, tokens or confidential business conditions, while aggregate session counts are often sufficient to locate a pool imbalance. When deeper inspection is necessary, use the database owner's approved access and retention policy. Avoid publishing full activity output in a public ticket. A good incident record can say that one worker group retained most connections and several requests waited on locks without copying private statements. Preserve only the additional detail needed to explain ownership and progress, and distinguish an observed state from a conclusion about whether the session is safe to interrupt.
BEGIN READ ONLY;
SET LOCAL statement_timeout = '5s';

SELECT application_name, usename, state, wait_event_type, count(*) AS sessions
FROM pg_stat_activity
WHERE backend_type = 'client backend'
  AND datname = current_database()
GROUP BY application_name, usename, state, wait_event_type
ORDER BY sessions DESC
LIMIT 30;

COMMIT;
-- Visibility depends on the role. Keep names and results private.
-- No query bodies or connection secrets are selected.Calculate the fleet budget, including deployment overlap
The connection budget belongs to the whole database service, not one application process. Count workers, application instances, scheduled jobs, migration tools, administrative access and any connection poolers. Multiply per-process pool ceilings by the number of processes that can run simultaneously. Include rolling deployment overlap, temporary investigation tools and recovery workers. In a hypothetical example, six workers with twelve connections each can request seventy-two slots. If six replacement workers start before the old group exits, the application can request one hundred forty-four before counting anything else. These figures illustrate multiplication; they are not suggested settings or measurements from a Hostwatch installation.
Read the actual configured limits and operational reserve. PostgreSQL's connection settings reference documents max_connections and reserved connection facilities, with version-specific details and resource implications. Preserve a management path that remains usable when ordinary application admission fills. Do not allocate every available slot to the busiest frontend and assume maintenance will somehow fit later. A larger limit can admit more competing work while increasing resource pressure, so it needs a capacity argument. First compare intended concurrency with useful throughput and the database's tested workload. If multiplying pools already exceeds the agreed budget, fix that arithmetic before treating the server limit as the primary defect.
Find connections retained beyond their useful work
A connection can remain assigned while the application performs unrelated network calls or waits for a user action. Trace where the code acquires and releases the connection, including error handling and cancellation. The useful question is how long the scarce resource remains owned, not only how long a single query executes. Inspect recent code changes, exceptional paths and worker lifetimes. A missing release on an uncommon failure can accumulate slowly until a busy hour exposes it. Compare acquired, returned and currently borrowed connections if the client library provides those counters. Keep each metric's scope and reset behavior with the observation.
Make ownership narrow in the implementation. Acquire a connection when database work is ready, complete the required transaction, and release through the library's supported lifecycle even when an exception occurs. Avoid holding a transaction open while contacting an unrelated service when the business semantics permit a different arrangement. Do not invent a universal rewrite for every application: some operations require carefully designed coordination. Use a controlled fixture to exercise the actual error paths, then observe whether borrowed connections return to baseline. Restarting the process can release retained sessions temporarily, but the recovery note should distinguish that immediate effect from a correction to the ownership bug.
Separate idle sessions from idle transactions
An idle pooled session can be an intentional reusable resource. An idle session inside an unfinished transaction deserves a different investigation because the transaction can retain locks and other database state. Preserve transaction age, application owner and the request that opened it where available. Do not rank sessions only by how long the TCP connection has existed. A long-lived healthy pool and a much younger stalled business transaction can require opposite responses. Compare the transaction lifecycle with application deadlines and error handling. The most useful clue can be a worker that stopped doing database work but never completed the transaction it already began.
PostgreSQL's client defaults reference documents statement, lock and idle-in-transaction timeout settings with different scopes. Review them for the installed version and workload rather than applying one short global value during an outage. A timeout can bound one failure mode while interrupting legitimate maintenance or confusing a pool that handles disconnections poorly. Prefer a deliberate role or session policy where suitable, with known application error behavior. Record what each timeout limits and what the caller does afterward. The test should demonstrate that abandoned work stops retaining resources without turning ordinary long operations into a new source of failures.
Trace blockers before interrupting a session
When work is waiting on locks, distinguish the waiting sessions from the session preventing progress. PostgreSQL provides system information functions, including pg_blocking_pids, for identifying blocking relationships. Use a bounded, authorized query and preserve the relevant transaction ages and owners. A list of many blocked clients does not imply that all those clients are defective. One unfinished transaction can create a queue behind it, and increasing connection capacity can simply make that queue larger. Map the blocking relationship to the business operation and recent change timeline before selecting a recovery action.
Interrupting database work has application consequences. Cancelling a statement, terminating a session and restarting a database have different scopes, and a client may have an uncertain outcome after losing its response. Involve the transaction owner and use the service's established recovery procedure. A generic list of old backend identifiers is not sufficient authority to terminate them all. Preserve the chosen target and reason, then verify that waiting work progresses and that affected operations reconcile correctly. Where the application can safely avoid a long lock hold through a narrower transaction or changed maintenance plan, turn that finding into a reviewed software or operating change after immediate recovery.
BEGIN READ ONLY;
SET LOCAL statement_timeout = '5s';

SELECT pid, application_name, state,
       now() - xact_start AS transaction_age,
       pg_blocking_pids(pid) AS blocking_pids
FROM pg_stat_activity
WHERE datname = current_database()
  AND backend_type = 'client backend'
  AND wait_event_type = 'Lock'
  AND pid <> pg_backend_pid()
ORDER BY xact_start NULLS LAST
LIMIT 20;

COMMIT;
-- A missing privilege or NULL field is a visibility limit.
-- Do not poll blocking functions in a tight loop or terminate by age alone.
Understand what a pooler is pooling
A pooler introduces another set of limits and queues. PgBouncer's configuration reference distinguishes client admission, server pool sizing and pooling modes. Session pooling keeps a server connection for a client session; transaction pooling releases it at a transaction boundary. A large allowed client count therefore does not mean the database has the same number of active backend connections, and a small backend pool can still make many clients wait. Read the settings for the actual database and user combinations, including overrides. Record pooler identity and observation time so a shared default is not mistaken for every effective pool configuration.
Changing pooling mode can affect application behavior. Review the pooler's feature compatibility table and the installed client stack for session state, prepared statements and other assumptions before adopting transaction pooling. Features and support depend on versions and configuration. A connection-efficiency improvement is useful only when the application's semantics remain correct. Reproduce representative transactions through the proposed arrangement, including failures and reconnects, before moving live traffic. Keep the previous configuration and an explicit recovery path. Adding a pooler is an architectural change with operational ownership, rather than a universal switch that automatically repairs excessive concurrency or long-lived transactions in the application.
Bound admission before waiting consumes the application
A pool acquisition timeout limits how long one caller waits, but an unlimited population of waiting callers can still exhaust application memory or request slots. Give the component a bounded admission policy and an understandable overload result. Separate the number of original user operations from repeated attempts, because retries can amplify demand while successful completions decline. If the database needs fewer concurrent operations to recover, raising frontend worker count may make the situation worse. Observe the relationship between admitted work, database progress and end-to-end latency. The goal is stable useful throughput within the capacity the dependency can actually provide.
Apply budgets across the full operation. Include time spent waiting for a pool, connecting, executing and returning the result. Ensure the application stops or reconciles work appropriately when the caller's deadline expires. A request that times out at the edge can leave a database operation continuing in the background; repeating it blindly can consume more connections or duplicate a mutation. Use supported cancellation and idempotency mechanisms where required. During recovery, reduce unnecessary amplification and restore traffic gradually through the reviewed controls. Avoid declaring success solely because pool wait errors fell after the application began rejecting every customer request before it reached the pool.
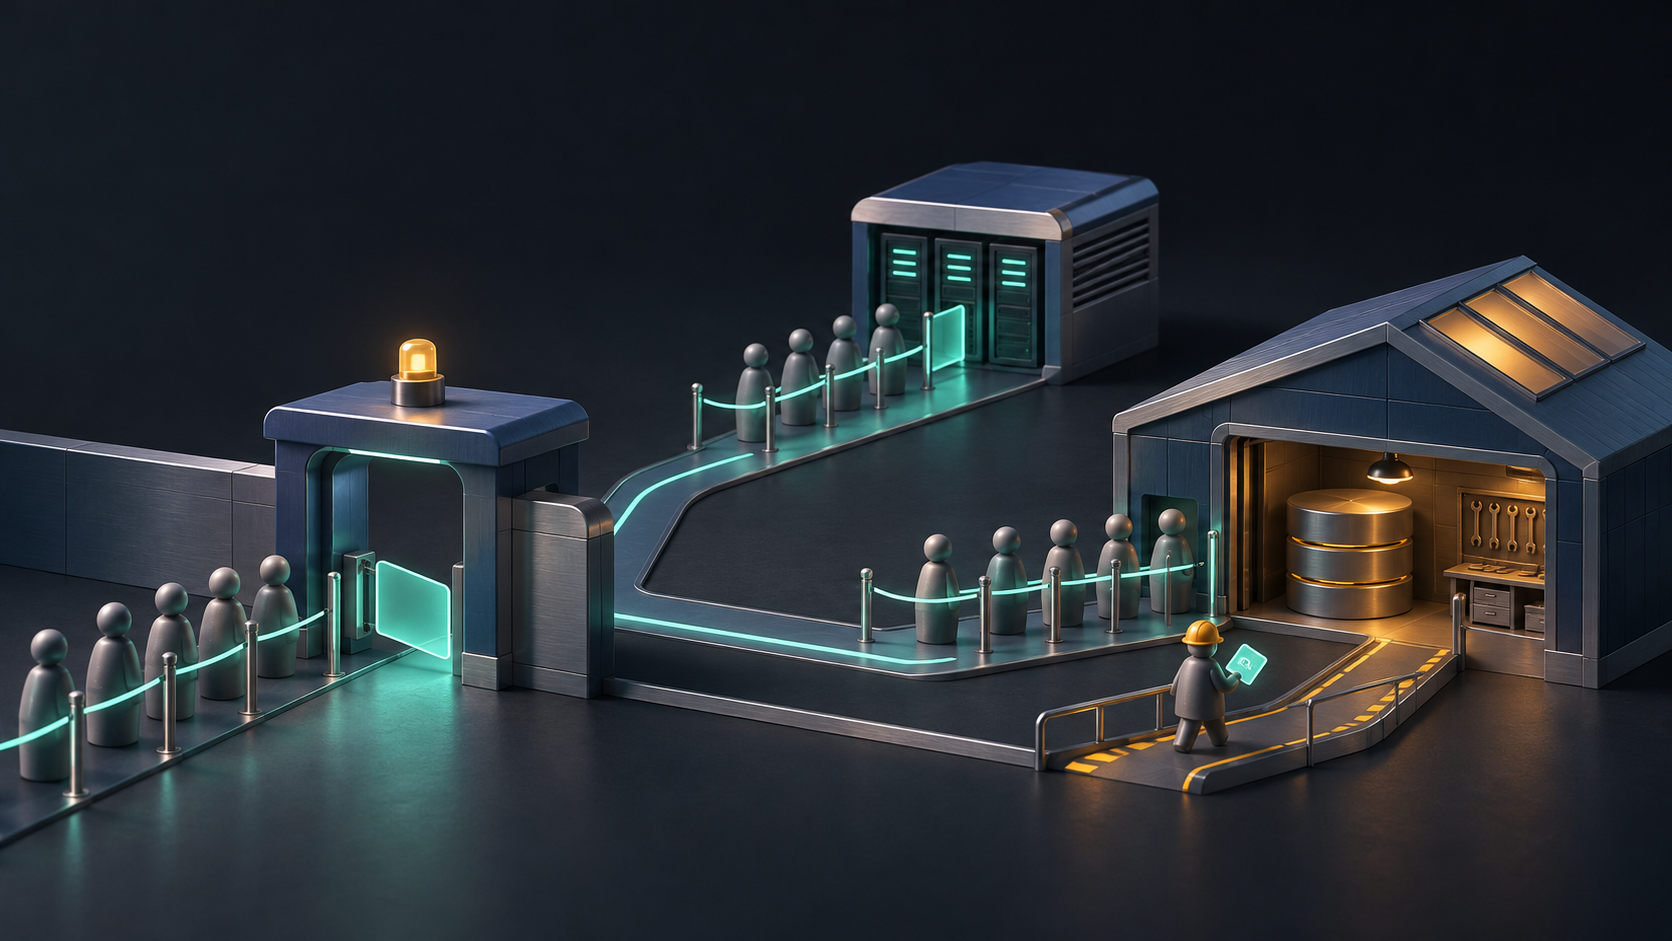
Reserve capacity for migrations and scheduled work
Background jobs can consume the same scarce connections as interactive requests. Inventory their concurrency, pool settings, scheduling window and expected transaction duration. A migration tool starting many workers during a frontend deployment can create a peak that ordinary traffic tests never exercised. Keep the capacity plan tied to what can run at the same time, not just what usually runs. For expensive work, choose an explicit admission limit and maintenance policy appropriate to its business requirements. A job that must finish eventually can often use a different queue and deadline from a customer request that must complete promptly.
Manual releases still need this coordination. Record whether a software change adjusts pool size, worker count, transaction behavior or migration concurrency. Check compatibility with the existing database budget before applying the component update. A source-control commit alone does not establish that any of these settings reached the serving process. After the release, read the configured runtime and observe actual session ownership. Preserve the previous application configuration for a targeted rollback where supported. This turns a vague statement such as the database became busy after deploy into a testable account of which component increased its connection demand and whether that increase fit the agreed reserve.
Use Hostwatch for placement and surrounding pressure
Hostwatch helps connect a failing application to its configured server and component, with the resource and service observations available for that installation. That context can show whether a database incident coincided with memory pressure, a deployment or another workload on the same host. It does not automatically establish which SQL transaction owns a database lock or expose every client's private pool queue. Those conclusions need their own database or application evidence. Keep the evidence boundaries visible so a quiet host CPU chart does not become a claim that the database is healthy, and a busy chart does not identify a blocker by itself.
Combine the observations in one incident window. Record the affected flow, component identity, pool acquisition evidence, database session state and any installed operating change. If the database is managed by another provider, identify that owner and use the supported diagnostics available there. A missing privilege or unavailable pool metric remains an explicit limitation. Do not fill the gap with a guessed connection count. The handoff should tell the next operator which queue was measured, what changed and what remains unknown. This preserves the practical value of the fleet view while keeping specialized database decisions grounded in the layer that can actually explain them.
Verify recovery with completions and returned connections
Re-run the affected low-impact workflow and observe useful completions, pool waiting and database progress during the same interval. Check that borrowed connections return, idle transactions remain bounded under the chosen policy and administrative access still works. Watch the behavior during a controlled error as well as a successful request. A leak correction that only handles the happy path is incomplete. If the incident involved a blocker, confirm that the blocked workload resumes and that uncertain business operations are reconciled. Keep a short comparison with the original evidence rather than replacing the incident record with a fresh green dashboard screenshot.
Finish with a concrete change to the operating budget or implementation. That may be a corrected connection lifecycle, a smaller aggregate pool, bounded job concurrency, a transaction fix or a justified capacity increase. Record the selected scope and the evidence supporting it. Avoid turning emergency session interruptions into an undocumented routine. The next incident should begin with known pool owners, deliberate reserves and a clear distinction between acquisition, connection and execution waits. Database reliability improves when the team can explain how many operations it admits, how long each resource remains owned and how successful completion returns those resources for the next caller.
- Identify pool acquisition, login, lock and execution waits separately.
- Count aggregate pool demand, jobs and release overlap against the database budget.
- Inspect retained connections and unfinished transactions through authorized evidence.
- Review pooler mode and application compatibility before changing the architecture.
- Verify completions, returned connections and remaining management reserve.
Locate the actual queue, budget the entire fleet and shorten unnecessary connection ownership. Verify recovery through useful completions and returned resources, with deliberate administrative reserve.