
Disk full with gigabytes free: mounts, inodes and the space you cannot see
Free space on the wrong filesystem cannot save a failing write. Trace the destination mount, file entries, open deleted files and container storage before choosing a scoped recovery.
Published 5 November 2026. Hostwatch engineering review; implementation limits are stated below.
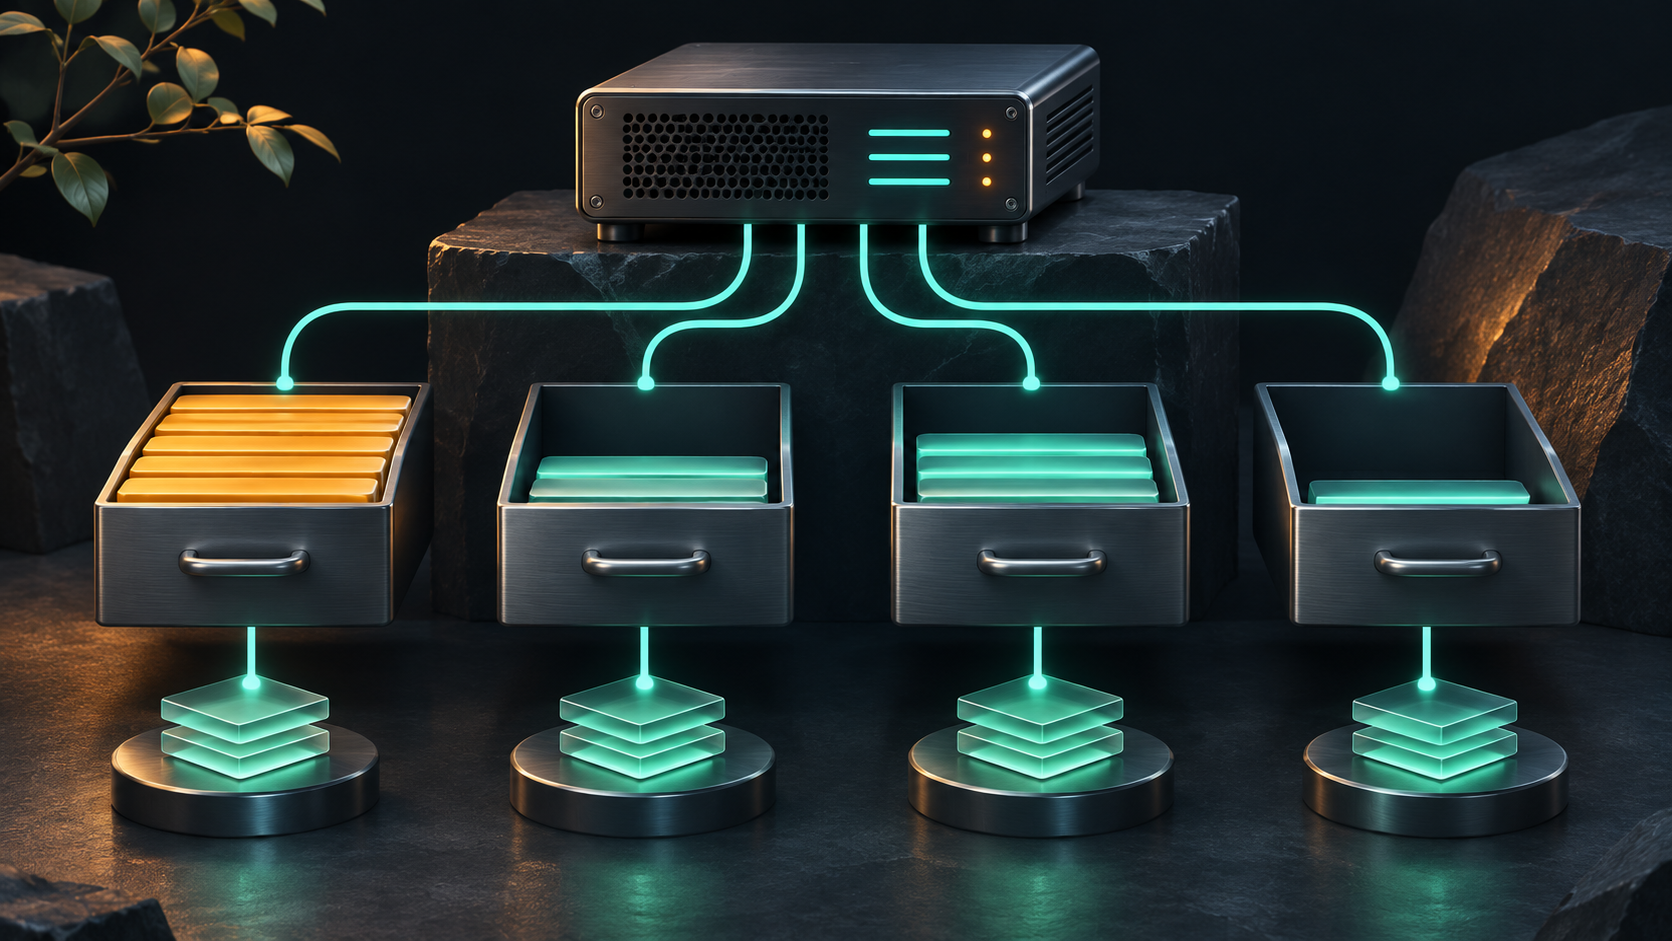
Diagnose the destination filesystem, not the server total
A server can have plenty of free storage and still fail to create the next file an application needs. The relevant limit belongs to the filesystem, quota and resource used by that write. A large data disk does not rescue a full root filesystem when a build writes temporary files under root. Free bytes do not create more file entries on a filesystem whose inode pool is exhausted. Begin with the failing operation and its actual destination path. Record the error, runtime identity, time and expected mount before deciding that the machine needs a larger disk or a broad cleanup command.
Use a concrete application example: a backup writes into one directory, a container stores its image layers elsewhere and the database uses a mounted data volume. Those three operations can encounter different capacity limits on the same host. A dashboard card labeled Disk may describe only the configured primary filesystem. Additional mounted-volume evidence helps, but it still needs a connection to the application's write path. The useful initial question is where the failed write would allocate storage. Once that destination is known, inspect its bytes, file entries, quota and mount state rather than averaging unrelated disks into a reassuring server-wide total.
Map the path to a real mount
Use the host's mount inventory and a path-specific space check to identify the relevant filesystem. The examples in this article are read-only Linux diagnostics; replace the sample path with the application's reviewed location. GNU's df documentation describes reporting space for the filesystem containing a given file or directory. Include filesystem type and mount target when recording the result. Two paths that look unrelated can share one filesystem, while a familiar directory can belong to a newly mounted device. Avoid assuming that the directory name alone proves where its writes currently land.
Check whether the expected mount is present at all. If a data volume failed to mount after reboot, an application may create files in the underlying directory on the root filesystem. Mounting the intended volume later can hide those earlier files without reclaiming their root-filesystem blocks. This is one reason a directory-size scan and a filesystem counter can appear to disagree. Do not unmount a live application volume casually to investigate. Establish the writer and recovery procedure first, then use the appropriate maintenance process. A missing or misplaced mount is a routing problem for storage, not something that deleting arbitrary large files reliably fixes.
# Replace this with the application's actual write destination.
TARGET=/srv/data
findmnt --target "$TARGET" --output TARGET,SOURCE,FSTYPE
df -hT "$TARGET"
df -i "$TARGET"
# Record each output's mount and timestamp, not just its percentage.Check file entries as well as bytes
A workload can create millions of small files and consume the available inode pool long before it uses all available bytes. Session files, extracted packages, generated thumbnails and poorly bounded caches are common patterns to inspect. Run a path-specific inode check and compare it with byte capacity. Keep the filesystem type in the result, because allocation behavior differs between filesystems. An inode diagnosis should come from the reported resource and workload evidence, not from the assumption that every no-space error has the same cause. The error message and application identity help decide whether a quota or another allocation constraint also needs investigation.
If file entries are the constraint, removing one very large archive may free many bytes but only one file entry. A suitable remedy instead targets an identified collection of expired small files under the application's retention policy. Determine which process owns their lifecycle and whether it has a supported expiry operation. Preserve active sessions, queued work and recovery material. Then fix the growth rule that created the accumulation. A one-time count reduction without a bounded retention mechanism often produces the same incident again. The useful verification includes available file entries, successful file creation through the application and evidence that the relevant collection is no longer growing without limit.
A deleted name can still occupy storage
An open file can remain allocated after its directory entry has been removed. The Linux unlink manual explains that storage is released after the last relevant open reference is closed. This is particularly useful when a log was removed while its writer kept the file open. A normal directory walk no longer sees the name, while filesystem usage remains high. Inspect open unlinked files through authorized administration and keep the output private, because process names and file paths can reveal application information. Identify the owning process and allocation before choosing a recovery action.
For a logging process, the supported reopen or rotation procedure may release the old file without restarting the entire service. A database or application data file requires a different analysis; do not assume every open unlinked file is disposable logging. Record which file is held, how large its allocation is and why the owner can safely release it. After the documented action, check that the process writes to the intended current file and that filesystem usage changes as expected. Deleting the same pathname repeatedly cannot close an existing descriptor. This diagnosis turns a confusing discrepancy into a specific process-lifecycle problem with a verifiable endpoint.
# Can be expensive on a busy host; inspect once, not in a tight loop.
# Process names and paths can be sensitive. Keep the output private.
sudo lsof -nP +L1
# Correlate the process, device and allocation with the affected mount.
# This command neither closes a file nor reclaims its allocation.
Understand what directory scans can and cannot explain
Filesystem counters and a directory walk answer different questions. A walk can miss files hidden by another mount, paths it cannot read or data outside the chosen subtree. Snapshots, shared extents, reserved space and filesystem metadata can also affect how allocation relates to visible file sizes. Hard links create another reason to interpret apparent totals carefully. Preserve access errors rather than silently presenting an incomplete scan as a complete inventory. If you use a filesystem-specific diagnostic, check its documented meaning for that filesystem and storage layout. A confident subtraction between incompatible measurements is not a reliable list of bytes safe to reclaim.
Large scans also have an operating cost. Start with the affected mount and a shallow directory view rather than recursively searching every mounted path during an outage. Keep the scan on the intended filesystem where appropriate, use a low-priority process for expensive inspection and avoid stacking several competing scans from different operators. A network mount can block on a remote failure, and a busy local volume can experience additional pressure from metadata reads. The sample shallow scan is an optional escalation after counters and mount identity are known. It is not a monitoring loop to run every few seconds until the dashboard changes.
# Choose the reviewed mount or directory before starting.
TARGET=/srv/data
sudo nice -n 19 ionice -c 3 du -x -h --max-depth=1 "$TARGET"
# -x stays on one filesystem. This may still be a costly full traversal.
# Low priority does not make an unlimited scan free.Container storage is not the same as application data
A container host has several storage classes: immutable image layers, build cache, writable container layers, logs and persistent application volumes or bind mounts. Their ownership and recovery value differ. A previous image can be useful rollback material. A cache can be regenerable yet expensive to rebuild under pressure. A volume can contain the only current database. Docker's volume documentation describes persistence outside an individual container's lifecycle. Use that boundary to map the workload's durable data, not to assume that any item described as unused by a runtime is safe to remove from the application owner's recovery plan.
Inspect the runtime's scoped disk-usage report and the application's configured mounts. Confirm whether a large writable layer indicates that the application is writing data outside its intended persistent location. Distinguish a stopped disposable test container from a retained recovery candidate. Broad prune commands are poor diagnostic tools because they combine several removal decisions before the operator has identified the actual constraint. Prefer a preview and a named target under an approved retention policy. If a cleanup is proposed through Hostwatch, keep the measured path classification and protected-data boundaries visible. The objective is to reclaim the right allocation while retaining what the serving application and its documented rollback still need.
Reserve space for the operation that comes next
The next deployment, backup or source extraction can require temporary space in addition to its final output. A compressed archive may expand substantially. A container build can hold source, intermediate layers and its finished image at the same time. A backup can coexist with the previous verified archive until retention safely removes it. Budget these stages on the filesystem that actually stores them. A statement that the final artifact fits is not enough. The operation should check the relevant reserve before beginning and stop with a clear result when its configured budget cannot be met.
Some filesystems also reserve capacity for privileged use or internal purposes, so free blocks and blocks available to the application's user can differ. Do not change reservation settings simply to make a percentage look better. First establish which counter the application and monitoring card report, which identity performs the write and what recovery reserve the service requires. Keep a margin appropriate to the workload's growth and temporary operations. A nearly full filesystem can make ordinary maintenance harder even before every last block is consumed. The useful reserve is an operating decision tied to known work, rather than an arbitrary percentage copied across every disk in the fleet.
Measure growth and estimate time to exhaustion
A capacity snapshot explains the present; a growth rate helps decide urgency. Compare the same filesystem and counter over a known interval, and account for cleanup or backup events that make growth discontinuous. As a simple hypothetical example, twenty gigabytes available with a sustained net growth of two gigabytes per hour suggests about ten hours before exhaustion under unchanged conditions. That estimate is a planning aid, not a guarantee. Bursty logs, a backup or a large build can consume the remaining margin much sooner. Keep the observation window and known next operation beside the estimate so another operator can judge its relevance.
Use both absolute reserve and rate of change when defining operational alerts. A large volume at a high utilization percentage can have substantial runway, while a smaller volume with a comfortable-looking percentage can have little time left under its current workload. Missing samples and a changed mount identity invalidate a naive trend. Avoid joining points from different devices after a remount or replacement as if they described one continuous filesystem. In a service incident, inspect whether increased error logging itself is accelerating disk growth. This connects traffic pressure to a secondary failure mode and can justify a scoped logging or retention adjustment alongside the application response.
Reclaim through the owner of the data
Once the allocation is identified, choose the application or runtime's supported lifecycle operation. An expired backup, abandoned build workspace, derived cache and active database each need different rules. Preserve the evidence that makes a candidate eligible, including age, current references and recovery requirements. If data must be moved to independent storage first, verify the destination copy and its restore usefulness before retiring the original. The presence of another file with the same name is not sufficient proof of a usable backup. Coordinate active writers and use a consistent application-aware method where the store requires one.
Treat infrastructure growth as a separate plan from cleanup. Extending a cloud block device does not necessarily expand every partition, filesystem or quota that sits above it. The correct procedure depends on the actual storage stack and filesystem. Re-read the path-specific counters after an approved resize instead of assuming that a provider console's larger device size reached the application. Keep the previous configuration and recovery constraints recorded. A capacity incident is a poor time to guess the device name for a destructive storage command. The practical remediation should follow the identified layout and the documentation of the layer being changed, with a result the application can demonstrate afterward.
Read Hostwatch's volume evidence within its scope
Hostwatch's current Linux collector reports supported additional mounted local whole-filesystem volumes separately from the configured primary disk. It avoids treating bind mounts as extra independent disks and excludes pseudo filesystems, selected system paths and container-runtime storage paths from that additional-volume enumeration. This makes the display more useful than a single root percentage, but it is not a complete inventory of every attached provider disk, subvolume layout or remote filesystem. An unmounted device does not become a healthy mounted-volume card. Confirm unusual layouts through host-side administration and retain an explicit unavailable state where collection does not cover them.
Use the observed mount, capacity and timestamp to connect a service's configured data path with its actual storage. Do not infer inode availability, application quotas or open deleted-file allocations from a byte-only card; those need their own measurements. The web and native views share the available volume evidence, while the operating system remains the source for deeper filesystem diagnostics. This distinction is useful during handoff. An operator can say which mount is under pressure and which additional check established its cause, without claiming that a general monitoring screen automatically detected every layer of the storage failure.
Verify the application and the reserve after remediation
Repeat the relevant mount, byte and inode checks, then verify the important write through the application's normal supported flow. Confirm that data is landing on the intended filesystem and that the writer has the expected identity and permissions. If a log reopen released allocation, check current logging. If retention removed expired items, verify that current data and required rollback material remain. If capacity was expanded, confirm that the application-visible filesystem or quota actually grew. A changed free-space number is useful evidence, but it does not prove that the original failed operation can now complete or that recovery material survived the intervention.
Finish with a short causal record: the destination mount, constrained resource, owning process or data collection, approved action and observed result. Include the remaining reserve, growth pattern and responsibility for preventing recurrence. The next useful improvement might be bounded cache expiry, a pre-build disk check, log rotation that reopens correctly, a monitored data mount or a verified backup lifecycle. The goal is more than postponing the next full-disk alert. It is to make the relationship between application writes and real storage understandable enough that the next operator can choose a specific remedy before an unrelated free-space total sends the investigation in the wrong direction.
- Map the failed write to its actual mounted filesystem.
- Inspect bytes, inodes and relevant quotas with separate evidence.
- Investigate open unlinked files before assuming a directory scan is complete.
- Reclaim or resize through the owning layer with a recovery plan.
- Verify application writes and the reserve for the next operation.
Diagnose the filesystem that receives the write. Confirm bytes, inodes and ownership before remediation, then verify application writes and the reserve needed for the next operation.